d-Matrix Links Raptor Chips to NVIDIA’s Architecture in New Race to Accelerate AI Inference
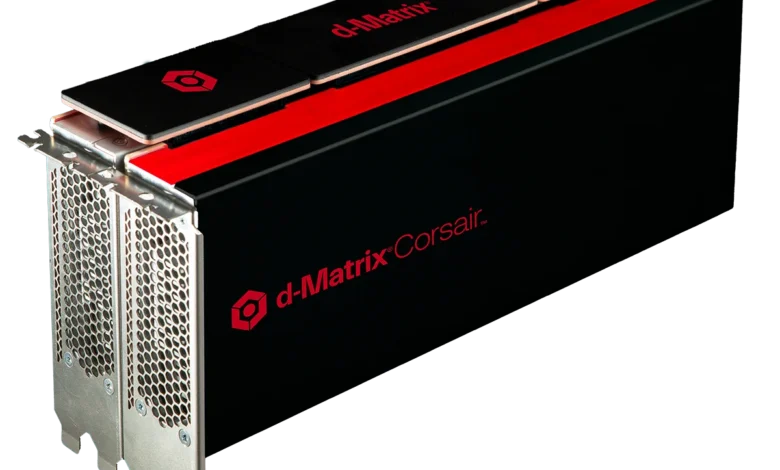
Chip startup d-Matrix has entered a new phase in the race to build artificial intelligence infrastructure after announcing that it will adopt NVIDIA’s NVLink Fusion technology to connect its next-generation Raptor processors directly to NVIDIA’s data center architecture.
The move targets one of the fastest-growing areas of the AI market: inference—running models after they have been trained to perform real-world tasks such as conversation, code generation, voice assistants and smart services requiring immediate responses.
Technical Summary
- d-Matrix will use NVLink Fusion to connect Raptor to NVIDIA’s architecture.
- The primary focus is low-latency inference workloads.
- The final design for Raptor is expected by the end of 2026.
- Integrated systems are expected to appear during 2027.
Follow developments in chips and infrastructure through the Technology section, and news about models through the Artificial Intelligence section.
What Did d-Matrix Announce?
According to the company’s announcement and details published by NVIDIA on September 10, 2026, d-Matrix will use NVLink Fusion to connect Raptor XPU units to NVIDIA’s rack-scale architecture, including NVLink for high-speed connectivity and Spectrum-X for large-scale networking, along with the MGX architecture.
The two companies said the goal is to accelerate the transition of custom chips from the design stage to systems that can be deployed at scale, while reducing the engineering risks associated with building an integrated architecture from scratch.
Why Has “Inference” Become the Focus of Competition?
During the early years of the generative AI boom, most attention focused on training large-scale models. But as these models have spread into everyday applications, competition has gradually shifted toward the cost and speed of running them.
Inference requires processing a huge number of requests with low latency, opening the door to specialized architectures that seek to reduce energy consumption and costs while maintaining performance.
Raptor Within NVIDIA’s Architecture
Reuters reported that the final design of the Raptor chips is expected to be completed by the end of 2026, while integrated systems are expected to begin appearing in 2027. These solutions are aimed at applications such as chatbots, coding assistants, voice agents and AI services that require rapid responses.
d-Matrix is also working with Astera Labs to develop high-speed data paths within these systems, in an effort to build a platform capable of handling large inference workloads efficiently.
A Startup With Significant Backing and Investment
d-Matrix has attracted growing investor interest. Reuters noted that Microsoft had backed the company since a $110 million funding round in 2023, before it raised $450 million in 2025 at a valuation of about $2 billion. The company also began shipping its first AI-specific chips in late 2024.
What Does the Partnership Mean for the Market?
The most important aspect of the announcement is that it reflects a shift in AI infrastructure strategy: NVIDIA is not limiting itself to selling its own processing units, but is expanding its ecosystem to allow custom chips from other companies to operate within its architecture. This could give service providers greater flexibility in choosing the most suitable processor for each type of workload, while retaining the networking and surrounding systems that have become essential elements of modern data centers.
Frequently Asked Questions About d-Matrix and Raptor
What Does NVLink Fusion Add to Raptor?
The technology enables Raptor processors designed for inference to connect to NVIDIA’s high-speed architecture inside data centers, rather than requiring an entirely separate connectivity architecture to be built.
What Does Inference Mean in Artificial Intelligence?
Inference is the stage in which a model is run after training to handle real-world requests such as conversation, code generation and voice assistance.
When Are the Integrated Systems Expected to Appear?
According to the published information, the Raptor design is targeted for completion by the end of 2026, with integrated systems expected to appear during 2027.
For broader context on the computing market, also read our coverage in Artificial Intelligence.
Featured image: d-Matrix Media Kit.
Sources
Primary source: Reuters. Official technical source: NVIDIA Blog.